Unit 2 · 8 teaching hours · 24 min read
Interpolation and Approximation
What the syllabus asks for 8
- Introduction and uniqueness
- Errors in polynomial interpolation
- Lagrange interpolation
- Newton's interpolation with divided differences
- Newton's forward and backward difference formulas (equal spacing)
- Cubic spline interpolation
- Least-squares approximation
- Seeing the ideas: one polynomial, divided differences, Runge's warning and the best-fit line
An experiment gives you the temperature at 6, 9, 12 and 15 hours; what was it at 10:30? A table of \sin x lists whole degrees; what is \sin 5 ^{\circ}?
Interpolation constructs a function that passes exactly through the known data points and reads off intermediate values. Approximation (least squares) instead fits a simple curve near noisy data without passing through every point.
- Interpolating polynomials: Lagrange, Newton divided differences, Newton forward and backward differences.
- The error of polynomial interpolation.
- Cubic spline interpolation.
- Least-squares fitting of lines, exponentials and polynomials.
2.1 Introduction and uniqueness
Given n + 1 distinct points (x_{0} ,\ y_{0}) ,\ \ldots ,\ (x_{n} ,\ y_{n}), there is exactly one polynomial of degree at most n through all of them.
Lagrange's and Newton's formulas are different ways to write the same polynomial, so they must give the same value; that is a handy check.
Estimating inside [x_{0} ,\ x_{n}] is interpolation; estimating outside is extrapolation, which is far less reliable.
2.2 Errors in polynomial interpolation
If f has n + 1 continuous derivatives and P_{n} interpolates f at x_{0} \ldots x_{n}, then for some ξ in the interval
The product term is small near the middle of the data and large near the ends, so interpolate near the centre.
Raising the degree does not always help: for equally spaced points and some functions (Runge's example \frac{1}{(1 + 25 x^{2})}) the error at the ends grows with n. This is one reason to prefer splines for many points.
2.3 Lagrange interpolation
Each point has a basis polynomial L_{i} (x) = \frac{\Pi_{j \neq i} (x - x_{j})}{(x_{i} - x_{j})}, which is 1 at x_{i} and 0 at all other nodes; then P_{n} (x) = \sum y_{i} L_{i} (x). It works for unequal spacing, but adding a point means starting again.
Data:
| i | x_{i} | y_{i} = \ln x_{i} |
|---|---|---|
| 0 | 1 | 0.000000 |
| 1 | 2 | 0.693147 |
| 2 | 3 | 1.098612 |
| 3 | 4 | 1.386294 |
For x = 2.5 and four nodes the weights L_{0} \ldots L_{3} are -0.0625, 0.5625, 0.5625, -0.0625 (they always sum to 1). Then P_{3} (2.5) = 0.921221. The true \ln 2.5 = 0.916291, so the error is 0.004931.
The theoretical bound uses f'''' (x) = - \frac{6}{x^{4}}, at most 6 on [1, 4], and the product |(2.5 − 1 ) (2.5 - 2) (2.5 - 3) ( 2.5 − 4)| = 0.5625, giving |\mathrm{error}| \leq \left( \frac{6}{4 !} \right) (0.5625) = 0.140625.
The actual error is well inside the bound. Using only the three nearest nodes 2, 3, 4 gives 0.910603 with error 0.005688: more points here helped only slightly.
2.4 Newton's interpolation with divided differences
Divided differences are defined by f [x_{i}] = y_{i} ,\ f [x_{i} ,\ x_{i+1}] = \frac{(f [x_{i+1}] - f [x_{i}])}{(x_{i+1} - x_{i})}, and so on, each order dividing by the total span. The interpolating polynomial is
Adding a new data point adds one term and one table diagonal; nothing already computed is wasted. Works for unequal spacing.
| x_{i} | f [x_{i}] | f [x_{i} ,\ x_{i+1}] | f[·,·,·] | f[·,·,·,·] |
|---|---|---|---|---|
| 1 | 0.000000 | 0.693147 | -0.143841 | 0.028317 |
| 2 | 0.693147 | 0.405465 | -0.058892 | |
| 3 | 1.098612 | 0.287682 | | |
| 4 | 1.386294 | | | |
The top diagonal gives the coefficients 0.000000, 0.693147, -0.143841, 0.028317. Then P_{3} (2.5) = 0 + 0.693147 (1.5) - 0.143841 (1.5) (0.5) + 0.028317 (1.5) (0.5) (- 0.5) = 0.921221, identical to the Lagrange value, as it must be.
2.5 Newton's forward and backward difference formulas (equal spacing)
For equally spaced nodes with step h define forward differences \Delta y_{0} = y_{1} - y_{0} ,\ \Delta^{2} y_{0} = \Delta y_{1} - \Delta y_{0}, and so on. With u = \frac{(x - x_{0})}{h}:
Forward: y (x) \approx y_{0} + u \Delta y_{0} + \frac{u (u - 1)}{2 !} \Delta^{2} y_{0} + \frac{u (u - 1) (u - 2)}{3 !} \Delta^{3} y_{0} + \ldots
Use it near the start of the table. Near the end, use the backward formula with u = \frac{(x - x_{n})}{h}, the last entry of each difference column (\nabla):
Backward: y (x) \approx y_{n} + u \nabla y_{n} + \frac{u (u + 1)}{2 !} \nabla^{2} y_{n} + \frac{u (u + 1) (u + 2)}{3 !} \nabla^{3} y_{n} + \ldots
| x ^{\circ} | y = \sin x | \Delta y | \Delta^{2} y | \Delta^{3} y | \Delta^{4} y |
|---|---|---|---|---|---|
| 0 | 0.0000 | 0.1736 | -0.0052 | -0.0052 | 0.0004 |
| 10 | 0.1736 | 0.1684 | -0.0104 | -0.0048 | |
| 20 | 0.3420 | 0.1580 | -0.0152 | | |
| 30 | 0.5000 | 0.1428 | | | |
| 40 | 0.6428 | | | | |
\sin 5 ^{\circ} by the forward formula: h = 10 ,\ u = \frac{5 - 0}{10} = 0.5. The top-row differences are 0.0000, 0.1736, -0.0052, -0.0052, 0.0004. The result is \sin 5 ^{\circ} \approx 0.08711; the true value is 0.08716.
\sin 35 ^{\circ} by the backward formula: u = \frac{35 - 40}{10} = - 0.5. The bottom-diagonal differences are 0.6428, 0.1428, -0.0152, -0.0048, 0.0004, giving \sin 35 ^{\circ} \approx 0.57358; the true value is 0.57358.
The differences become small and nearly constant at the fourth order, a sign that a quartic fits well. The forward result is off in the fourth decimal because the table itself is rounded to four decimals and differences amplify that rounding.
Choosing a formula. Divided differences for unequal spacing; forward formula for a point near the beginning; backward near the end; for the middle use central-difference formulas (Gauss, Stirling, not required here).
2.6 Cubic spline interpolation
A single high-degree polynomial through many points can oscillate.
A cubic spline instead uses a different cubic on each interval [x_{i} ,\ x_{i+1}], joined so that the function, its first derivative and its second derivative are continuous at every interior node.
It is smooth to the eye and well behaved, and is the mathematical form of a draughtsman's flexible ruler.
With n intervals there are 4 n unknown coefficients. Interpolation (2 n conditions) plus continuity of S' and S'' at the n - 1 interior nodes (2 n - 2) leaves two conditions; for a natural spline we set S'' = 0 at both ends.
Method. Let M_{i} = S'' (x_{i}) and h_{i} = x_{i+1} - x_{i}. The continuity of S' gives, for each interior node \ast i \ast,
a tridiagonal system. On each interval, with t = x - x_{i},
S (x) = y_{i} + b_{i} t + \left( \frac{M_{i}}{2} \right) t^{2} + \left( \frac{(M_{i+1} - M_{i})}{(6 h_{i})} \right) t^{3}, where b_{i} = \frac{(y_{i+1} - y_{i})}{h_{i}} - \frac{h_{i} (2 M_{i} + M_{i+1})}{6}.
With h = 1 the two interior equations are 4 M_{1} + M_{2} = 6 (2 - 1) = 6 and M_{1} + 4 M_{2} = 6 (- 1 - 2) = - 18 (with M_{0} = M_{3} = 0, using index 0 to 3 for the four nodes).
Solving gives the second derivatives M = (0.00000 ,\ 2.80000 ,\ - 5.20000 ,\ 0.00000). The pieces:
| interval | a | b | c | d (S = a + b t + c t^{2} + d t^{3} ,\ t = x - x_{i}) |
|---|---|---|---|---|
| [1, 2] | 2.00000 | 0.53333 | 0.00000 | 0.46667 |
| [2, 3] | 3.00000 | 1.93333 | 1.40000 | -1.33333 |
| [3, 4] | 5.00000 | 0.73333 | -2.60000 | 0.86667 |
Then S (1.5) = 2.32500 and S (2.5) = 4.15000. (A straight line through the neighbours of 2.5 would give 4.0, but the spline bends to reflect the whole data set.) The results agree with SciPy's CubicSpline(bc_type="natural").
2.7 Least-squares approximation
When data come from measurement they carry noise and passing through every point is pointless. The least-squares method chooses the curve that minimises the sum of squared vertical residuals S = \sum (y_{i} - f (x_{i}))^{2}.
Straight line y = a + bx
Setting \frac{\partial S}{\partial a} = \frac{\partial S}{\partial b} = 0 gives the normal equations
\sum y = n a + b \sum x ,\ \sum x y = a \sum x + b \sum x^{2},
so b = \frac{n \sum x y - \sum x \sum y}{n \sum x^{2} - \left( \sum x \right)^{2}} and a = \frac{\sum y - b \sum x}{n}.
| x | y | x^{2} | x y |
|---|---|---|---|
| 1 | 2.2 | 1 | 2.2 |
| 2 | 2.8 | 4 | 5.6 |
| 3 | 3.6 | 9 | 10.8 |
| 4 | 4.5 | 16 | 18.0 |
| 5 | 5.1 | 25 | 25.5 |
| \sum = 15 | 18.2 | 55 | 62.1 |
\sum x = 15 ,\ \sum y = 18.2 ,\ \sum x^{2} = 55 ,\ \sum x y = 62.1 with n = 5. Then b = \frac{5 \times 62.1 - 15 \times 18.2}{(5 \times 55 - 15^{2})} = 0.7500 and a = \frac{18.2 - 0.7500 \times 15}{5} = 1.3900.
The line is y = 1.3900 + 0.7500 x. The residual sum of squares is 0.0270 and R^{2} = 0.9952, an excellent fit. Predicting x = 6 gives 5.890 (extrapolation, so treat it with caution).
Non-linear data: reduction to linear form
| Model | Transformation | Fit line to |
|---|---|---|
| y = A e^{B x} | \ln y = \ln A + Bx | (x ,\ \ln y) |
| y = A x^{B} | \ln y = \ln A + B \ln x | (\ln x ,\ \ln y) |
| y = \frac{1}{a + b x} | \frac{1}{y} = a + b x | \left( x ,\ \frac{1}{y} \right) |
| y = a + \frac{b}{x} | y = a + b·(1/x) | \left( \frac{1}{x} ,\ y \right) |
| x | y | \ln y | x·ln y |
|---|---|---|---|
| 1 | 2.7 | 0.9933 | 0.9933 |
| 2 | 4.0 | 1.3863 | 2.7726 |
| 3 | 6.1 | 1.8083 | 5.4249 |
| 4 | 9.2 | 2.2192 | 8.8768 |
| 5 | 13.5 | 2.6027 | 13.0134 |
Fitting a straight line to (x ,\ \ln y) gives B = 0.4052 and \ln A = 0.5864, so A = 1.7975 and y = 1.7975 e^{0.4052 x}. The prediction at x = 6 is 20.44.
Note that this minimises the error in \ln y, not in y, which weights small values more; it is the standard quick method.
Polynomial (quadratic) fit
For y = a + b x + c x^{2} the normal equations are \sum y = n a + b \sum x + c \sum x^{2} ,\ \sum x y = a \sum x + b \sum x^{2} + c \sum x^{3} ,\ \sum x^{2} y = a \sum x^{2} + b \sum x^{3} + c \sum x^{4}.
For the line data above, solving gives (a ,\ b ,\ c) = (1.4400 ,\ 0.7071 ,\ 0.0071): the x^{2} coefficient is nearly zero, confirming that the straight line was enough.
2.8 Seeing the ideas: one polynomial, divided differences, Runge's warning and the best-fit line
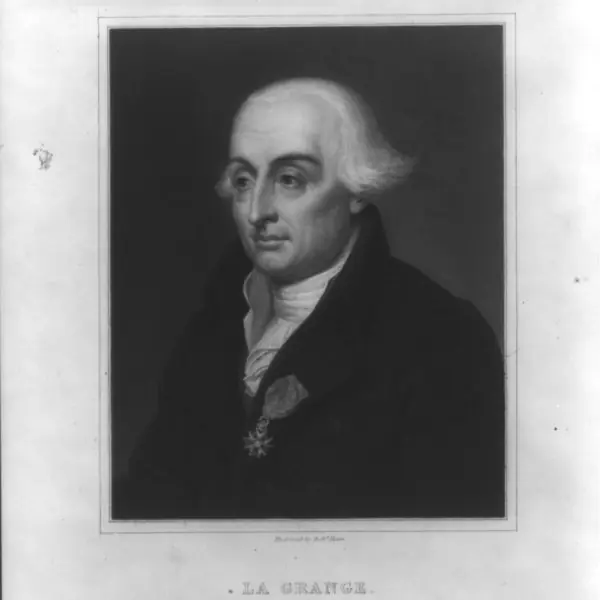
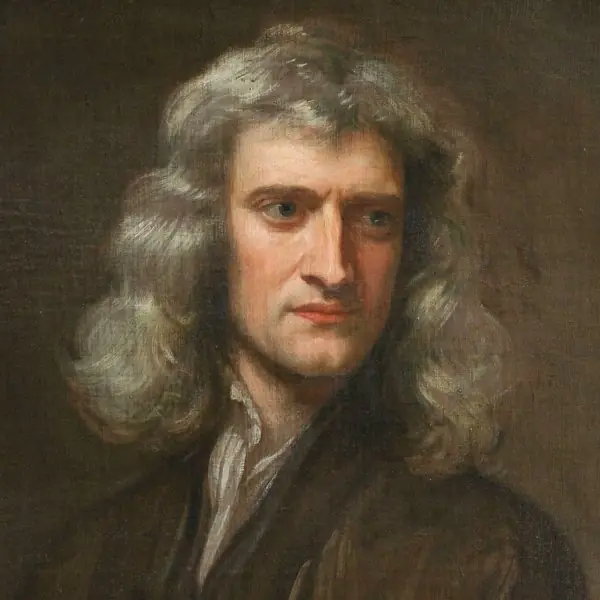
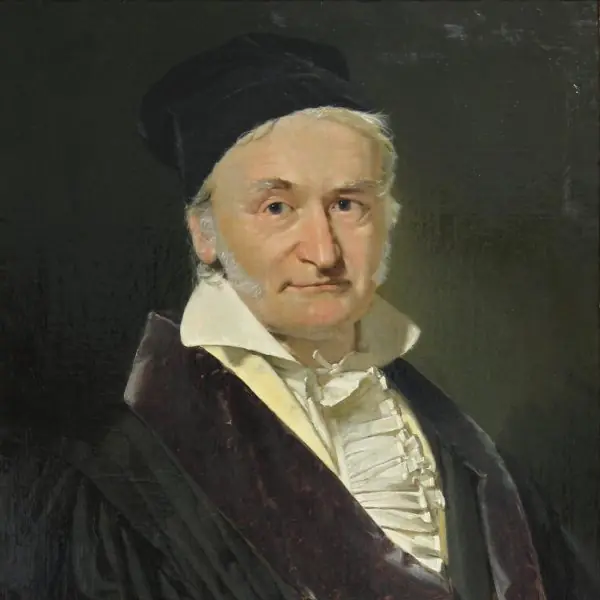
The three people in Plate 2.1 gave their names to the three tools of this unit. The figures that follow show what each tool does on real numbers.


2.8.1 Eight uses of interpolation and curve fitting
- Filling gaps in tables. A weather office records temperature every three hours, and interpolation estimates the value at any time between readings. The same idea fills missing rows in a data sheet. It is the first step of most data cleaning.
- Estimating values from old tables. Before calculators, logarithm and trigonometry tables gave values at fixed steps, and interpolation gave the rest. Engineers still read steam tables and statistical tables this way. The error formula tells how close the answer is.
- Smooth curves in computer graphics. Splines pass through control points and give smooth roads, fonts and animation paths. A letter in a font file is a few spline pieces. Cubic splines are used because they avoid the wiggles seen in Figure 2.3.
- Image and video resizing. When a photo is enlarged, the computer must invent the new pixels by interpolating between neighbours. Bilinear and bicubic interpolation are the common methods. Mobile phone zoom depends on them.
- Trend lines and forecasting. A least-squares line through exam marks, sales or population counts shows the trend and predicts the next value. A Nepali college can project next year's admissions. The residual sum tells how reliable the line is.
- Calibrating instruments. A sensor gives voltage while the true reading is temperature or pressure. A fitted line or curve converts voltage to the true unit. Every digital thermometer does this inside.
- Numerical integration and differentiation. Rules such as Simpson's are derived by fitting a polynomial through a few points and integrating it. Interpolation is therefore the base of the next unit. Without it there would be no Newton-Cotes formulas.
- Machine learning and data science. Linear regression is least squares, and curve fitting underlies many models that learn from noisy data. Understanding it explains overfitting, which is the modern form of Runge's wiggles. The idea of balance between fit and smoothness appears everywhere.
Formula and fact sheet
- Error: f (x) - P_{n} (x) = \frac{f^{(n+1)} (\xi)}{(n + 1) !} \cdot \Pi (x - x_{i}).
- Lagrange: P (x) = \frac{\sum y_{i} \Pi_{j \neq i} (x - x_{j})}{(x_{i} - x_{j})}.
- Newton divided differences: P = f [x_{0}] + fx₀,x₁ + …
- Forward: u = \frac{(x - x_{0})}{h}, terms \frac{u (u - 1) \ldots}{k}! \Delta^{k} y_{0}. Backward: u = \frac{(x - x_{n})}{h}, terms \frac{u (u + 1) \ldots}{k}! \nabla^{k} y_{n}.
- Spline: continuity of S ,\ S' ,\ S''; natural ends S'' = 0; tridiagonal system for M_{i}.
- Line fit: b = \frac{n \sum x y - \sum x \sum y}{n \sum x^{2} - \left( \sum x \right)^{2}} ,\ a = \frac{\sum y - b \sum x}{n}.
Chapter summary
- Through n + 1 points there is one polynomial of degree ≤ n; Lagrange, Newton divided-difference and Newton difference formulas all give it.
- The error depends on the (n + 1)th derivative and the product of distances to the nodes: interpolate near the centre and avoid very high degrees.
- Cubic splines give a smooth piecewise fit by solving a tridiagonal system.
- Least squares fits noisy data by minimising squared residuals; many non-linear models reduce to straight lines after a transformation.
Practice
- State the interpolation error formula and explain why it is smallest near the centre of the data.
- Use Lagrange's formula with nodes 1, 2, 3, 4 and \ln x to estimate \ln 2.5. Find the error.
- Build the divided-difference table for the same data and confirm the value.
- From the 10 ^{\circ} table of \sin x, estimate \sin 5 ^{\circ} (forward) and \sin 35 ^{\circ} (backward).
- Why is the forward formula used near the beginning of a table and the backward near the end?
- Find the natural cubic spline value at x = 2.5 for the points (1, 2), (2, 3), (3, 5), (4, 4).
- Fit y = a + b x to (1, 2.2), (2, 2.8), (3, 3.6), (4, 4.5), (5, 5.1). Predict y at x = 6.
- Fit y = A e^{B x} to (1, 2.7), (2, 4.0), (3, 6.1), (4, 9.2), (5, 13.5).
- Distinguish interpolation from least-squares approximation.
- What is Runge's phenomenon, and how do splines avoid it?
Answers and worked solutions
1. f (x) - P_{n} (x) = \frac{f^{(n+1)} (\xi) (x - x_{0}) \ldots (x - x_{n})}{(n + 1) !}. Near the middle the factors |x − x_{i} \mid are smaller (some nodes lie on either side), whereas near the ends all distances are large, so the product and the error are bigger.
2. The weights at 2.5 are - 0.0625 ,\ 0.5625 ,\ 0.5625 ,\ - 0.0625 ;\ P_{3} (2.5) = 0.921221, true 0.916291, error 0.004931 (bound 0.140625).
3. The table in Section 2.4 gives coefficients 0.000000, 0.693147, -0.143841, 0.028317; evaluating at 2.5 gives 0.921221, the same as Lagrange.
4. Forward with u = 0.5: \sin 5 ^{\circ} \approx 0.08711 (true 0.08716). Backward with u = - 0.5: \sin 35 ^{\circ} \approx 0.57358 (true 0.57358).
5. Forward differences use the top row of the table, which has all its later columns available only if the point is near the start; near the end the top-row differences of high order don't exist or are poorly centred, while the bottom diagonal (backward differences) has them and reaches back from the end.
6. M = (0.00000 ,\ 2.80000 ,\ - 5.20000 ,\ 0.00000) ,\ S (2.5) = 4.15000 from the piece on [2, 3]: 3 + 1.93333 (0.5) + 1.4 (0.25) - 1.33333 (0.125) = 4.15000.
7. \sum x = 15 ,\ \sum y = 18.2 ,\ \sum x^{2} = 55 ,\ \sum x y = 62.1 ;\ b = 0.7500 ,\ a = 1.3900; at x = 6 ,\ y = 5.890.
8. \ln y values in Section 2.7 ;\ B = 0.4052 ,\ \ln A = 0.5864 ,\ A = 1.7975: y = 1.7975 e^{0.4052 x}.
9. Interpolation reproduces the data points exactly and is suited to exact (or very accurate) data; least squares gives a smoother curve that need not pass through any point and is suited to noisy data.
10. For equally spaced nodes, a high-degree interpolating polynomial may oscillate wildly near the interval ends (for example \frac{1}{(1 + 25 x^{2})}).
A spline uses low-degree cubic pieces, so a local change affects only nearby intervals and no big oscillations build up.
Model answers: medium (5 marks) and long (10 marks) questions
Q1 (5 marks). Using Newton's divided-difference formula, estimate \ln 3 from \ln 1 ,\ \ln 2 ,\ \ln 4 and \ln 6. Estimate the error.
Data. x = 1 ,\ 2 ,\ 4 ,\ 6 ;\ f = 0 ,\ 0.69315 ,\ 1.38629 ,\ 1.79176.
| x | f | 1st | 2nd | 3rd |
|---|---|---|---|---|
| 1 | 0.00000 | |||
| 0.69315 | ||||
| 2 | 0.69315 | -0.11552 | ||
| 0.34657 | 0.01591 | |||
| 4 | 1.38629 | -0.03596 | ||
| 0.20273 | ||||
| 6 | 1.79176 |
Newton form. P (x) = 0 + 0.69315 (x - 1) - 0.11552 (x - 1) (x - 2) + 0.01591 (x - 1) (x - 2) (x - 4) (Figure 2.2). At x = 3: 0.69315 (2) - 0.11552 (2) (1) + 0.01591 (2) (1) (- 1) = 1.38630 - 0.23104 - 0.03182 = 1.12344 (about 1.1234).
The true \ln 3 = 1.09861, so the actual error is 0.0248.
Error formula. f (x) - P (x) = \frac{f'''' (x i)}{4 !} x (x - 1) (x - 2) (x - 4) (x - 6).
Here f'''' = - \frac{6}{x^{4}} and the product at 3 is 2 x 1 x (- 1) x (- 3) = 6, so the error magnitude is \left( \frac{6}{x i^{4}} \right) \left( \frac{6}{24} \right) = \frac{1.5}{x i^{4}}; the observed 0.0248 corresponds to xi = 2.79, inside [1, 6], as the theory requires.
Conclusion the estimate is accurate to about two decimals; a closer, centred set of points would be better.
Q2 (5 marks). Fit a straight line y = a + b x by least squares to (1, 2.1), (2, 3.9), (3, 6.2), (4, 7.8), (5, 10.1) and predict y at x = 6.
Normal equations. Sum y = n a + b sum x; sum x y = a sum x + b sum x^{2}.
| x | y | x^{2} | x y |
|---|---|---|---|
| 1 | 2.1 | 1 | 2.1 |
| 2 | 3.9 | 4 | 7.8 |
| 3 | 6.2 | 9 | 18.6 |
| 4 | 7.8 | 16 | 31.2 |
| 5 | 10.1 | 25 | 50.5 |
| 15 | 30.1 | 55 | 110.2 |
b = \frac{n \sum x y - \sum x \sum y}{n \sum x^{2} - \left( \sum x \right)^{2}} = \frac{5 x 110.2 - 15 x 30.1}{5 x 55 - 225} = \frac{551 - 451.5}{50} = 1.99. a = \frac{30.1 - 1.99 x 15}{5} = 0.05.
The line is y = 0.05 + 1.99x (Figure 2.4). At x = 6: y = 0.05 + 11.94 = 11.99. The residuals are 0.06, -0.13, 0.18, -0.21, 0.10, so the sum of squares is 0.107.
Conclusion the very small S shows a strong linear trend, and the prediction one step outside the data is acceptable because it is an extrapolation of only one unit.
Q3 (10 marks). Explain polynomial interpolation. Derive the Lagrange and Newton forms, discuss the error and Runge's phenomenon, and compare interpolation with least-squares approximation.
Introduction. Given n + 1 distinct points (x0, y0) \ldots (x n ,\ y n), interpolation finds a function that passes through every point and uses it to estimate values between them.
There is exactly one polynomial of degree at most n through the points, so the Lagrange and Newton forms are the same polynomial written differently (Plate 2.1 names the founders).
Lagrange form. P (x) = sum of yi Li(x), where Li(x) = product over j not equal i of \dfrac{*x* - xj}{xi - xj} equals 1 at xi and 0 at other nodes. It is simple to write, but adding a point means recomputing every term.
Newton form. P (x) = f (x 0) + f (x 0 ,\ x 1) ( x - x0) + f (x 0 ,\ x 1 ,\ x 2) (x - x 0) ( x - x1) + ... where the coefficients are divided differences made by the table of Figure 2.2.
A new point adds one new term, so the work already done is kept. For equally spaced data the divided differences become forward or backward differences and the Gregory-Newton formulas are used.
Error. f (x) - P (x) = \frac{f^{n + 1} (x i)}{(n + 1) !} x (x - x 0) \ldots (x - x n). The product is small near the middle of the data and large near the ends, so interpolate near the centre.
In Figure 2.1 the cubic through four points of \ln x has error 0.0248 at x = 3 and 0.0322 at x = 5.
Runge's phenomenon. Raising the degree with equally spaced nodes does not always improve accuracy: for \frac{1}{(1 + 25 x^{2})} the degree-10 interpolant oscillates wildly near the ends (Figure 2.3).
Remedies are low-degree piecewise polynomials such as cubic splines (continuous first and second derivatives) or Chebyshev-spaced nodes.
Least squares. When data are noisy, passing through every point is wrong. Least squares chooses the curve minimising the sum of squared residuals; for a line, b = \frac{n \sum x y - \sum x \sum y}{n \sum x^{2} - \left( \sum x \right)^{2}} (Figure 2.4).
| Point | Interpolation | Least-squares fit |
|---|---|---|
| Passes through data | Exactly | Not required |
| Suitable for | Exact tables, noise-free values | Noisy measurements |
| Degree | Rises with number of points | Chosen by the user (low) |
| Risk | Oscillation (Runge) | Underfit if model poor |
| Typical use | Table look-up, graphics | Trend lines, calibration |
Conclusion. Use interpolation for accurate tabulated values within the range, using Newton's form for convenience and splines for many points; use least squares for measurement data. Extrapolation is less reliable than interpolation in both cases.