Unit 4 · 10 teaching hours · 23 min read
Software Design
What the syllabus asks for 5
- Design concepts
- Architectural design
- Procedural design with structured methods
- User interface design
- Design in pictures: people, patterns and diagrams
Requirements say what the system must do; design decides how. A good design makes code easy to understand, test and change; a bad one makes every change a risk.
This unit covers the fundamental design concepts, architectural styles, structured design methods, and user interface design.
- Design concepts: abstraction, architecture, patterns, modularity, cohesion and coupling, information hiding, functional independence, refinement.
- Architectural design: repository, client-server, layered models; modular decomposition.
- Procedural design using structured methods; design metrics.
- User interface design: HCI principles, information presentation, interface evaluation; design notation.
4.1 Design concepts
| Concept | Meaning |
|---|---|
| Abstraction | focus on essentials, suppress detail. Procedural abstraction: a named sequence of instructions (sort()); data abstraction: a named collection of data (a Student record); control abstraction: a mechanism (loops, iterators) |
| Architecture | the overall structure of the software: components, their properties and relationships |
| Patterns | a proven solution to a recurring design problem in a context (MVC, Observer, Singleton); the design equivalent of a recipe |
| Modularity | dividing the software into separately named and addressable components (modules) that are integrated to satisfy requirements |
| Information hiding | each module hides a design decision (its data structure, algorithm) behind a stable interface; changes stay local (Parnas) |
| Functional independence | each module has a single, well-defined purpose and little interaction with others; measured by cohesion and coupling |
| Refinement | stepwise elaboration (Wirth): start with a statement at a high level of abstraction and decompose it, step by step, into programming-language statements |
Modularity and cost. Breaking a problem into modules reduces the cost of understanding each, but increases the cost of integration.
Total cost is minimised at a moderate number of modules of moderate size; both extreme (one giant module; thousands of tiny ones) are costly.
Cohesion
Cohesion measures how strongly the elements within a module belong together. From best to worst:
| Level | Description | Example |
|---|---|---|
| Functional | all elements contribute to one task | calculate_tax() |
| Sequential | output of one part is input to the next | read → validate → format a record |
| Communicational | parts operate on the same data | update and print the same student record |
| Procedural | parts follow a sequence of control but are unrelated in data | a routine that opens files, then prints a header |
| Temporal | parts are done at the same time | initialise_everything() |
| Logical | parts do similar things selected by a flag | one output(type) function for printer, screen and file |
| Coincidental | parts are unrelated | a misc_utils module |
Coupling
Coupling measures the interdependence between modules. From loosest (best) to tightest (worst):
| Level | Description |
|---|---|
| Data | modules communicate only through simple parameters |
| Stamp | they pass a composite structure, of which only part is used |
| Control | one passes a flag that controls the logic of the other |
| External | both depend on an external format, protocol or device |
| Common | both share global data |
| Content | one modifies or jumps into the internals of the other |
Goal: high cohesion, low coupling. A design with high cohesion and low coupling is easier to understand, test and maintain, since a module can be changed or replaced with minimal effect elsewhere.
Module report() takes a mode flag (1, 2 or 3) and prints a student, a teacher or a course report using shared global arrays. It has logical cohesion and common/control coupling.
Redesign: three functions print_student(s), print_teacher(t), print_course(c) that receive the record they print as a parameter: each has functional cohesion and data coupling.
4.2 Architectural design
The software architecture is the structure of the system: major components and how they interact. Early architectural decisions strongly affect performance, security, maintainability and distribution. Common styles (models):
Repository model
Subsystems exchange data through a central shared database (repository), which they read and write.
Advantages efficient sharing of large data; subsystems need not know how others produce data; backup, security and consistency are centralised.
Disadvantages all subsystems must agree on one data model (compromises); evolution is hard (data format changes affect everything); the repository is a single point of failure.
Example IDEs, CASE tool sets, a hospital database shared by several departments.
Client-server model
The system is a set of servers that provide services (file, print, database, web) and clients that use them over a network.
Advantages distribution, easy to add servers, services can be replicated.
Disadvantages no shared data model so interchange can be inefficient, redundant management in each server, no central registry of names unless one is provided.
Examples web applications, e-mail, online banking. Two-tier: thin client with presentation on the client and the rest on the server; or three-tier: presentation, application logic and data in separate tiers (browser, application server, database).
Layered model
The system is organised into layers, each providing services to the layer above and using the layer below.
Advantages supports incremental development, changes to one layer only affect adjacent ones, replaceable layers.
Disadvantages strict layering is hard, and performance suffers when a request passes through many layers.
Examples the OSI network model, operating systems, a typical business application: UI → business logic → data access → database.
Model–view–controller (MVC) pattern
Separates the model (data and business rules), the view (presentation) and the controller (input handling). The same data may have many views, and changes in the model update all views. It is the basis of most web frameworks (Laravel, Django, Spring MVC).
Modular decomposition
A subsystem is further divided into modules.
Two strategies: object-oriented decomposition, into a set of loosely coupled objects with defined interfaces; and function-oriented (pipeline) decomposition, into functional modules that accept input and transform it into output, as in a data-flow pipeline (compiler: lexer → parser → code generator).
Pipelines are simple and reusable but need agreed data formats.
Control models
Centralised control (a manager module calls others: call-return, as in structured programs) versus event-based control (the system responds to events, as in GUIs and real-time systems).
4.3 Procedural design with structured methods
Structured design starts from a data-flow diagram (DFD) of the requirements and maps it to a structure chart, a hierarchy of modules in which each box is a module and arrows show calls and the data (and control flags) passed between them.
Two mapping strategies:
- Transform analysis: for a DFD with clear input, central transformation, and output flows. Identify the afferent (input) branches, the central transform, and the efferent (output) branches. Create a top-level controller module with branches for each.
- Transaction analysis: for a DFD where one input transaction triggers one of several flows; create a transaction centre module that reads the transaction type and dispatches to the appropriate module.
Guidelines: keep the module span (fan-out) to about 7 ± 2; aim for high fan-in for utility modules (reuse); depth of the hierarchy should be moderate; each module should be a few dozen lines at most.
Design metrics: fan-in and fan-out
Fan-in of a module = number of modules that call it; fan-out = number of modules it calls. The Henry–Kafura information-flow complexity of a module is
length × (fan-in × fan-out)²
where length is the size of the module in lines. A module of 6 lines with fan-in 3 and fan-out 2 scores 6 × (3 × 2)² = 216; the same size module with fan-in 1 and fan-out 1 scores 6 × 1 = 6.
The squared term means that a module with many connections to others (a design hot-spot) stands out, and tends to correlate with defects and with change effort. Values far above those of the other modules should be redesigned.
Procedural design notations
Detailed design is expressed with flowcharts, pseudo-code (program design language), structured English, decision tables and Nassi–Shneiderman diagrams.
Pseudo-code is the most usual: it uses the keywords of structured programming (IF … THEN … ELSE, WHILE, FOR, CASE) and informal language for the actions, so it can be read by non-programmers and converted line by line to code.
PROCEDURE issue_book(member, copy)
    IF member.card_expired THEN
        REPORT "card expired"; RETURN
    IF count_loans(member) >= 5 THEN
        REPORT "limit reached"; RETURN
    IF copy.reserved_for IS NOT member THEN
        REPORT "reserved"; RETURN
    CREATE loan(member, copy, today + 14 days)
    SET copy.status TO "on loan"
END PROCEDURE
4.4 User interface design
The user interface (UI) is the part of the system users meet; to them it is the system. A poor UI leads to errors and abandonment even when the functions are right.
Human–computer interaction principles
Design principles (Shneiderman's eight golden rules, Nielsen's heuristics): consistency (same actions, same terms), shortcuts for experts, informative feedback, closure (clear end to a sequence), error prevention and simple error handling, easy reversal of actions (undo), user in control, and reduced short-term memory load (recognition over recall; at most 7 ± 2 items).
Also user familiarity (use the users' concepts, not the computer's), minimal surprise, recoverability, user guidance (help, meaningful error messages) and user diversity (accessibility; Nepali Unicode support).
Interaction styles
| Style | Advantages | Disadvantages | Used for |
|---|---|---|---|
| Direct manipulation | quick to learn, immediate feedback | hard to program, screen-space | drag-and-drop, drawing |
| Menu selection | little typing, few errors | slow for experienced users | ATMs, forms |
| Form fill-in | simple entry, easy to learn | consumes screen space | data entry |
| Command language | powerful, flexible | hard to learn, error-prone | experts, scripting |
| Natural language | accessible | ambiguous, long | voice assistants, chatbots |
Information presentation
Separate the information from its presentation (MVC).
Choose the form by the type of information: numeric data as graphs and bar charts for trends, text for exact values; colour used sparingly (about 4 to 5 colours, redundantly coded for colour-blind users, with culturally appropriate meanings); alerts distinguishable and consistent; dynamic information shown as it changes.
Layout should follow a clear visual hierarchy.
Interface evaluation
Evaluate the interface with users: usability testing (observe real users doing tasks, measure time, errors, satisfaction), heuristic evaluation (experts check against guidelines), questionnaires, think-aloud sessions, video and logging.
Revise and re-test: UI design is iterative, and prototypes are essential. Typical metrics: learning time, task time, error rate, retention, subjective satisfaction. (Semester II's UX/UI Design book treats these in depth.)
4.5 Design in pictures: people, patterns and diagrams
Design is the step where the what of the SRS becomes the how of the program.
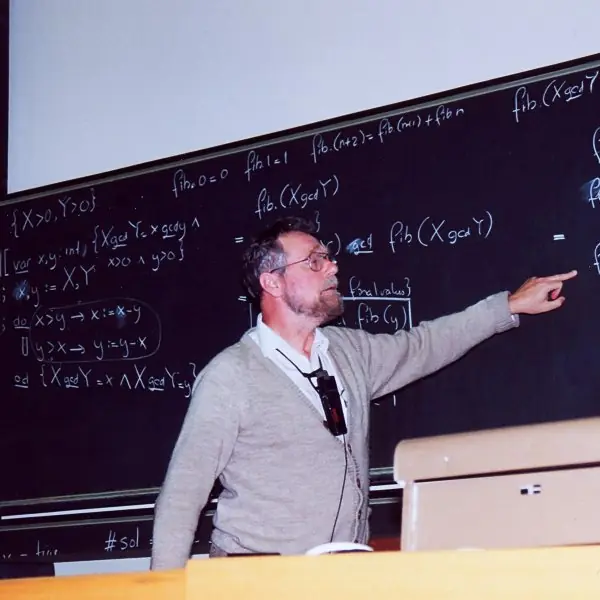
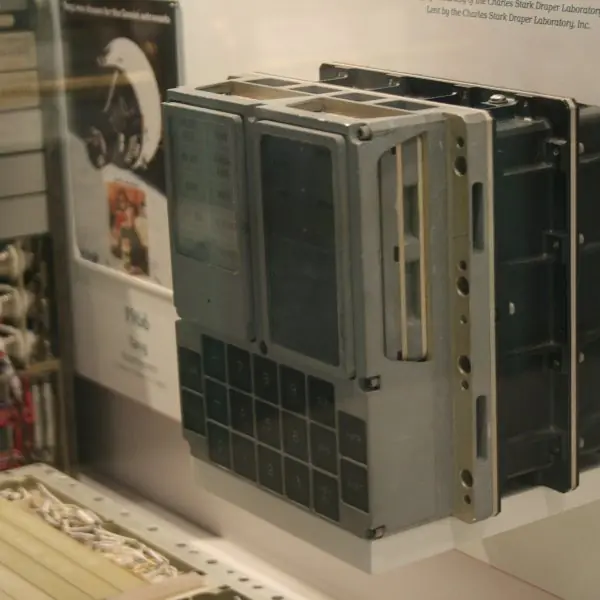
Plate 4.1 shows three people whose ideas shaped design (structured programming, conceptual integrity and a user interface built under extreme limits), and Figures 4.1 to 4.6 draw the architecture, the coupling and cohesion scales, a structure chart, a data flow diagram, a class diagram and a good error message.


4.5.1 Eight principles of good software design
- Abstraction. A designer works at the level of "what" a part does and hides "how" until later. A function
computeGpa()is used without knowing the formula inside, which keeps the big picture simple. Abstraction lets one person think about a large system at several levels, as in the data flow diagram of Figure 4.4. - Modularity. The system is split into modules that can be built, tested and replaced separately, as in the structure chart of Figure 4.3. Small modules are easy to understand, and several people can work on them at the same time. Too many tiny modules, however, raise the cost of joining them.
- High cohesion. Everything inside a module serves one purpose, such as calculating the grade point and nothing else. A cohesive module is easy to name, test and reuse. The cohesion ladder of Figure 4.2 ranks the different degrees.
- Low coupling. Modules depend on each other as little as possible and exchange only the data they need. When coupling is low, a change in one module rarely breaks another. Global variables and shared files create strong coupling and should be avoided.
- Information hiding. Each module keeps its design decisions, such as a data structure, private and shows only a small interface. If the marks are later stored in a different database, only that module changes. David Parnas proposed this rule in 1972.
- Separation of concerns. Different jobs are kept in different parts: presentation, business rules and data storage, as in the MVC pattern of Figure 4.1. The page layout can then change without touching the grading logic. This also lets specialists, such as a designer and a database expert, work independently.
- Reuse of proven patterns and components. Architectural styles and design patterns capture solutions that already worked, and libraries save effort. A Nepali team building a payment screen does better to reuse a tested payment library than to write its own. Reuse lowers cost and faults but each component must still be checked for fit.
- Design for change and testability. Requirements will change, so the design leaves room to change one decision cheaply and makes every module easy to test alone. Clear interfaces and a layered structure give this. The cost of change then stays near the lower end of Figure 1.1.
Formula and fact sheet
- Cohesion best → worst: functional, sequential, communicational, procedural, temporal, logical, coincidental.
- Coupling best → worst: data, stamp, control, external, common, content. Aim: high cohesion, low coupling.
- Henry–Kafura = length × (fan-in × fan-out)².
- Styles: repository, client-server, layered, MVC, pipeline.
- Transform analysis vs transaction analysis.
Chapter summary
- Design concepts (abstraction, modularity, information hiding, refinement, functional independence) aim at modules with high cohesion and low coupling.
- Architectural styles organise the system: repository, client-server, layered, MVC; modules are decomposed by objects or functions.
- Structured design maps DFDs to structure charts by transform or transaction analysis, with fan-in/fan-out metrics and pseudo-code for the detail.
- UI design follows HCI principles; the choice of interaction style and presentation depends on users and tasks, and is validated by evaluation.
Practice
- Explain abstraction, modularity and information hiding with examples.
- Rank the types of cohesion and coupling and explain why functional cohesion and data coupling are the best.
- A function
process(flag)does validation if flag = 1, saving if flag = 2, and printing if flag = 3. Identify its cohesion and coupling problems and fix them. - Compare the repository, client-server and layered models, with one advantage and disadvantage each.
- What is MVC, and why is it useful for web applications?
- Distinguish transform analysis and transaction analysis.
- Compute the Henry–Kafura complexity for a 10-line module with fan-in 2 and fan-out 3.
- List the HCI principles that apply to an ATM interface.
- How is a user interface evaluated?
Answers and worked solutions
1. Abstraction: use sort(list) without knowing the algorithm. Modularity: split a system into Billing, Inventory, Reports. Information hiding: a Stack hides whether it uses an array or a linked list; callers use only push and pop.
2. Cohesion: functional > sequential > communicational > procedural > temporal > logical > coincidental. Coupling: data > stamp > control > external > common > content (loosest first). Functional cohesion and data coupling make modules single-purpose and independent, so each can be understood, tested and changed separately.
3. Logical cohesion (unrelated tasks chosen by a flag) and control coupling (the caller controls the callee's logic). Fix by splitting into validate(), save() and print(), each with functional cohesion and data coupling.
4. Repository: shared data; but single point of failure and one data model. Client-server: distribution and scalability; but redundant management and no shared model. Layered: replaceable layers and incremental development; but performance cost across layers.
5. Model–view–controller separates data/rules, presentation and input handling. The UI can change (web, mobile) without changing business rules, and the same data can have several views; teams can work in parallel.
6. Transform analysis maps a DFD with distinct input, transform and output streams into a controller with input, process and output branches. Transaction analysis maps a DFD in which one input selects one of many flows into a dispatcher module and one module per transaction type.
7. 10 × (2 × 3)² = 10 × 36 = 360.
8. Consistency, informative feedback, error prevention and handling, ability to cancel/reverse, simplicity (menu selection), minimal short-term memory load, accessibility (language, large text), and security cues.
9. By usability tests with real users (time, errors, satisfaction), heuristic evaluation by experts, questionnaires, think-aloud sessions and logging; findings feed the next iteration.
Model answers: medium (5 marks) and long (10 marks) questions
Q1 (5 marks). Explain coupling and cohesion. Why should a good design have low coupling and high cohesion?
Introduction. Cohesion measures how strongly the elements inside one module belong together; coupling measures how strongly one module depends on others (Figure 4.2).
- Cohesion levels, worst to best. Coincidental (random parts), logical (similar kind of task, such as all input routines), temporal (executed at the same time, such as start-up code), procedural (steps in a given order), communicational (work on the same data), sequential (output of one is input of the next) and functional (one single task).
- Coupling levels, best to worst. Data (only needed values are passed), stamp (a whole record is passed), control (a flag decides the behaviour of another module), external, common (shared global data) and content (one module changes the inside of another).
- Example. A module
compute_gpa(marks, credits)that only returns a number is functionally cohesive and data coupled. A module that prints, saves and calculates, reading a global table, is coincidental and common coupled. - Why this is the goal. High cohesion makes a module understandable and reusable; low coupling means that a change in one module does not spread to others, so maintenance is cheaper and testing is simpler.
Conclusion. Good design aims at functional cohesion with data coupling.
Q2 (5 marks). State and explain the golden rules of user interface design.
Introduction. Shneiderman's eight golden rules summarise how a usable interface behaves (Figure 4.6).
- Strive for consistency. The same actions, words, colours and menus are used everywhere.
- Enable shortcuts. Frequent users get shortcuts, such as function keys, while novices keep the simple path.
- Give informative feedback. Every action gets a visible response, such as "Marks saved".
- Design dialogues with closure. A task has a clear beginning, middle and end, such as a confirmation page.
- Prevent errors and offer simple error handling. Disable invalid choices and give clear messages, such as "Marks must be from 0 to 100".
- Permit easy reversal. Undo and Cancel reduce the fear of mistakes.
- Keep the user in control. The user starts actions; the system responds.
- Reduce short-term memory load. Keep screens simple, use lists instead of recall, and show choices.
Conclusion. An interface that follows these rules is learned quickly, produces fewer errors and is accepted by users.
Q3 (10 marks). Explain software design. Describe the design concepts, the design process, and the architectural styles. Compare layered and client-server architectures.
Introduction. Software design is the activity that transforms the SRS into a blueprint from which programmers can write code.
It is done at two levels: architectural design (the major components and their relations) and detailed design (the algorithms and data of each component).
Design concepts (section 4.5.1). Abstraction, modularity, high cohesion, low coupling, information hiding, separation of concerns, reuse and design for change.
A design is judged by these, not by how clever it is; Brooks called the underlying quality conceptual integrity (Plate 4.1).
Design process.
- Study the SRS and identify the major subsystems.
- Choose an architectural style and describe the components and their interfaces.
- Specify each component's functions, data and interfaces (structure charts, class diagrams, data flow diagrams such as Figure 4.4).
- Design the data structures, database and algorithms.
- Design the user interface (Figure 4.6).
- Review the design against the SRS for completeness and for traceability, then record decisions.
Architectural styles.
Layered presentation, business logic and data layers, each using only the one below.
Client-server clients request services from one or more servers. Model-view-controller (Figure 4.1): separates data, display and control.
Pipe and filter data flows through a chain of transformations.
Repository components share a central data store.
| Aspect | Layered | Client-server |
|---|---|---|
| Idea | stack of layers, each hides the one below | many clients, central servers |
| Strength | easy to change a layer, good portability | central data, shared services, easy updates |
| Weakness | extra layers cost speed | server is a bottleneck and single point of failure |
| Example | web app: UI, logic, database | Nagarik App talking to government servers |
Metrics. Modules are judged by fan-in, fan-out and Henry-Kafura complexity (Figure 4.3: length 50, fan-in 3, fan-out 2 gives 50 x 36 = 1,800).
Conclusion. A design that is modular, cohesive, loosely coupled and layered is easy to build, test and maintain, which are the qualities that determine its cost over the life of the system.
Q4 (10 marks). Draw and explain a data flow diagram and a structure chart for a college result system. Show how the structure chart follows from the DFD.
Introduction. Structured design describes a system as a set of processes and the data that flows between them (DFD), and then converts this to a hierarchy of modules (structure chart).
Data flow diagram (Figure 4.4).
External entities Examiner (source of marks) and Student (receiver of results).
Processes 1 Validate marks, 2 Compute GPA and 3 Publish result.
Data stores D1 Marks and D2 Results.
Flows marks from Examiner to process 1; valid marks to D1; marks to process 2; GPA to D2; result to process 3, and the result sheet to the Student.
Rules: a process must have at least one input and one output, data never flows directly between two stores or two entities, and every flow has a name.
Levelling. The context diagram (level 0) shows the whole system as one process with the two entities; level 1 splits it into the three processes above, and each process can be exploded into level 2 if needed. Inputs and outputs must balance between levels.
Transform analysis (DFD to structure chart). Find the central transform, the processes that change input data into output data, then the afferent branch (bringing data in) and efferent branch (sending data out).
Here Read marks is the afferent branch, Compute GPA the central transform, and Print result the efferent branch. A Main module coordinates them (Figure 4.3).
The central transform calls lower modules Total credits and Calculate grade point.
| DFD element | Structure chart element |
|---|---|
| input flow and process 1 | Read marks (afferent module) |
| process 2 | Compute GPA (transform module) |
| process 3 and output flow | Print result (efferent module) |
| data flow arrow | data couple passed between modules |
Quality checks. Each module should have functional cohesion and data coupling; the fan-out should be 7 or fewer; the module Calculate grade point has fan-in 3, so its complexity (1,800 for 50 lines) should be watched.
Conclusion. The DFD captures what data transformations are needed, and the structure chart turns them into a modular design in which each box is a function that can be coded and tested separately.